 By Alex
Jalapeño inference benchmarks: faster, more efficient AI
OpenAI's first public Jalapeño results report higher performance per watt and lower latency across three open models, while leaving deployment and independent verification as the next tests.
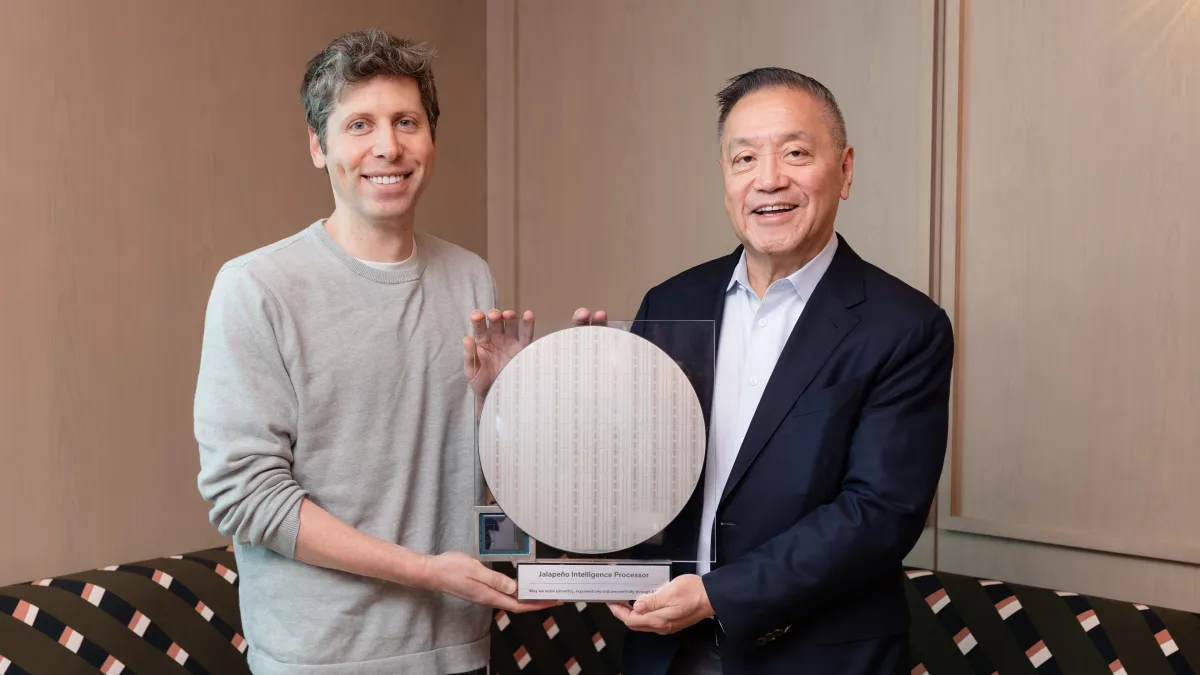
OpenAI's Jalapeño inference chip now has public performance data, not only a product announcement. In its first results report, OpenAI says Jalapeño delivered 1.5 to 1.9 times more AI work per watt at peak throughput and 1.7 to 3.6 times lower end-to-end latency than comparison systems across GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5 1T; operators should treat the figures as OpenAI's InferenceX measurements while waiting for independent production evidence.
Definition: Jalapeño is OpenAI's first custom inference chip, designed with its surrounding memory, networking, software, and serving system for language-model workloads.
Example: On the largest public model in the report, Kimi K2.5 1T, OpenAI reports approximately 1.5 times higher peak performance per watt and 3.4 times lower end-to-end latency than the comparison system.
Key takeaway: Jalapeño's first results matter because they claim a simultaneous throughput, efficiency, and latency improvement rather than a single peak-speed win.
Business impact: If later tests reproduce the gains in production, AI operators could serve more interactive work from the same power budget, but deployment scale and total cost remain unproven.
What did Jalapeño's first results actually measure?
Jalapeño's first results measure useful inference work at a matched user experience, combining throughput, power, and latency instead of reporting only a chip's theoretical peak. OpenAI used InferenceX, a public benchmark from SemiAnalysis, across the operating range from high-throughput serving to low-latency interactive use; operators should compare the full measurement conditions before turning the ratios into procurement claims.
Jalapeño's results span GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5 1T, which gives the report broader model coverage than a single-model demo. OpenAI reports 2.1 to 4.1 times higher performance for highly interactive workloads across the three models; that matters for AI agents that complete multi-step tasks because latency can accumulate across sequential inference calls.
| Reported measure | Jalapeño result versus comparison systems | Why it matters |
|---|---|---|
| Peak AI work per watt | 1.5× to 1.9× higher | More useful work from the same power budget |
| End-to-end latency | 1.7× to 3.6× lower | Faster responses for interactive applications |
| Highly interactive performance | 2.1× to 4.1× higher | Better headroom for multi-step workloads |
| Kimi K2.5 1T peak performance per watt | Approximately 1.5× higher | Shows the result on the largest named public model |
| Kimi K2.5 1T end-to-end latency | Approximately 3.4× lower | Shows the reported latency advantage on that model |
The table reports OpenAI's published comparisons, not a new independent test. The useful reading is the combination: Jalapeño claims to move the frontier on performance per watt and latency at the same time, while the comparison hardware, measurement boundary, and software configuration still determine how portable each ratio is.
Why does Jalapeño target both throughput and latency?
Jalapeño targets both throughput and latency because language-model inference changes bottlenecks between prompt processing and token generation. OpenAI describes prefill as compute-intensive, decode as more constrained by memory bandwidth, and communication as another source of idle time; operators evaluating inference hardware should therefore inspect the complete serving path rather than optimize for one phase in isolation.
Jalapeño's architecture keeps model state, including the KV cache used during generation, explicitly placed and local while compute, memory, and networking are activated for each inference phase. OpenAI says the connected system is designed to reduce data movement and communication delays; the practical takeaway is to measure time to first token, per-user token rate, sustained throughput, and power together.
Jalapeño is part of a full-stack AI automation architecture rather than an isolated processor swap. OpenAI says it is co-designing models, products, serving software, chips, memory, networking, and systems, so the reported result reflects an integrated system; buyers should ask whether a similar advantage is available with their own models, runtimes, and infrastructure constraints.
How strong are the model-by-model results?
Jalapeño's model-by-model results are strongest on the specific operating points OpenAI publishes, not as a universal ranking of every accelerator. On GPT-OSS 120B, OpenAI reports approximately 1.9 times higher peak mixed performance per kilowatt, 1.7 times lower end-to-end latency, and 2.7 times lower minimum time between tokens than the comparison system; operators should preserve the workload and power definitions when quoting those figures.
Jalapeño's DeepSeek R1 670B results show a different scale of reported latency advantage. OpenAI reports approximately 1.7 times higher peak performance per watt, 3.6 times lower end-to-end latency, and 4.1 times lower minimum time between tokens; the takeaway is that the architecture's claimed benefit is not limited to smaller or simpler public models.
Jalapeño's Kimi K2.5 1T results extend the published comparison to the largest model named in the report. OpenAI reports approximately 1.5 times higher peak performance per watt, 3.4 times lower end-to-end latency, and 3.8 times lower minimum time between tokens; operators should read that as evidence of model-scale coverage, not proof that every large model will behave identically.
What does the result say about OpenAI's infrastructure strategy?
Jalapeño signals that OpenAI is using custom silicon to control the economics of serving AI at scale, alongside continued use of NVIDIA and other partners. The result is strategically important because OpenAI says Jalapeño can deliver more useful work from the same power and hardware while supporting faster responses; infrastructure planners should view it as an additional capacity path, not an announced replacement for all external accelerators.
Jalapeño also shows how AI is entering the chip-development loop itself. OpenAI says the team moved from initial design to tapeout in nine months and used its models to explore implementations, shorten design and verification loops, and optimize arithmetic circuits; the concrete implication is a faster co-design cycle, while manufacturing, qualification, and software remain separate execution risks.
Jalapeño's programming model is intended to make parallel placement and scheduling tractable for both engineers and AI systems. OpenAI says Codex with GPT-Astra brought three open-weight models outside the original production plan to high performance within two months, and selected attention and mixture-of-experts blocks ran 1.5 to 1.8 times faster than existing human-written implementations; those block-level results do not establish the same gain for a full model.
When could Jalapeño reach production?
Jalapeño could begin deployment inside OpenAI's compute infrastructure by the end of 2026, according to OpenAI, while Gen 2 is already in development and Gen 3 is taking shape. OpenAI also says production qualification, software maturation, scale operations, and validation across more models are still underway; operators should treat the date as a planned deployment milestone rather than current availability.
Jalapeño's commercial case will depend on whether its measured advantage survives scale, reliability requirements, software changes, and future competitor hardware. TechCrunch's report notes that the comparison was against an NVIDIA Blackwell system and that Jalapeño is expected to deploy first in small volumes; the next useful evidence is independently reproducible production data.
The next checkpoint for Jalapeño is therefore not another headline ratio. It is a transparent technical report and real deployment measurements covering latency, tokens per user, throughput per kilowatt, memory behavior, interconnects, software compatibility, and total cost of ownership. Those details will determine whether Jalapeño is mainly an impressive first-generation design or a durable advantage for serving agentic AI.
Frequently asked questions
What do Jalapeño's first benchmarks show?
OpenAI reports that Jalapeño delivered 1.5 to 1.9 times more AI work per watt at peak throughput and 1.7 to 3.6 times lower end-to-end latency than the comparison systems across GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5 1T. For highly interactive workloads, OpenAI reports 2.1 to 4.1 times higher performance. These are OpenAI's measurements on the public InferenceX benchmark, not an independent product-wide certification.
Which models were tested on Jalapeño?
The published results cover GPT-OSS 120B, DeepSeek R1 670B, and Kimi K2.5 1T. OpenAI says the tests included models developed both inside and outside the company, so the results are not limited to one OpenAI model family. The largest named test is Kimi K2.5 1T, where OpenAI reports approximately 1.5 times higher peak performance per watt and 3.4 times lower end-to-end latency than the comparison system.
Is Jalapeño already deployed at scale?
No. OpenAI says it plans to begin deploying Jalapeño inside its compute infrastructure by the end of 2026, while production qualification, software maturity, scale operations, and validation across more models continue. The first results therefore describe a tested system and a deployment plan, not a completed fleet-wide rollout or a guarantee of customer-facing availability.
What should buyers verify before treating Jalapeño as a benchmark winner?
Buyers should wait for reproducible measurements that disclose the workload, batch size, latency target, power boundary, comparison hardware, memory behavior, networking, software stack, and total cost of ownership. OpenAI's results are useful evidence that one architecture can combine throughput and latency, but the tests were published by the chip's designer. Independent results and production data will show how much of the advantage survives real deployments and changing model workloads.
Alex
Founder & Lead AI Writer
Alex is the founder of Yowox and lead AI writer since 2024, breaking down complex information into clear, actionable insights for thousands of readers every day. Alex has built AI automation systems for businesses since 2024, focusing on AI agents, workflow automation, and business process optimization.
Save hours. Save thousands.
Practical guides, real workflows, and the latest AI and automation news that matters — straight to your inbox.


